换做是以前的我,一定是花几个钟头的时间,去每一条视频名字,copy & paste去一个文件档。突然灵机一动:我可以怎样用电脑帮我完成这项工作。
今天我要求Claude Code教我如何:
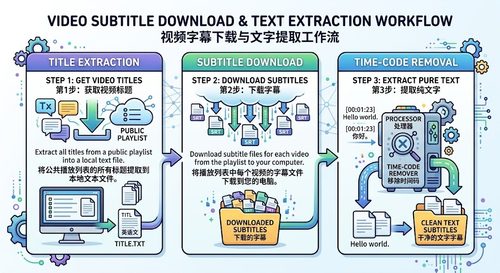
- 把一个公共列表所有视频的名字下载进本地电脑的title.txt文件。
- 把这公共列表里的视频字幕下载并储存在我的电脑。
- 我要移除时间码,只保留字幕。
所需的工具/软件:
- Macbook > Terminal
- Python
Claude Code指导的步骤如下:
- 在Brave,打开那个Youtube 列表,抄网址。
- 在Terminal,我开了一个新的directory。
mkdir youtubexj - 用以下Terminal命令找到字幕的语言。
yt-dlp –skip-download –list-subs –cookies-from-browser brave “https://www.youtube.com/watch?v=xxx”
OUTPUT:
[info] Available subtitles for RcyMAVmlWnI:
Language Name Formats
zh-TW Chinese (Taiwan) vtt, srt, ttml, srv3, srv2, srv1, json3 - 用以下命令下载字幕。
yt-dlp –skip-download
–write-subs –write-auto-sub
–sub-lang zh-TW
–sub-format vtt
–ignore-errors
–cookies-from-browser brave
–sleep-interval 3 –max-sleep-interval 6 \
-o “subs/%(title)s.%(ext)s” \
“https://www.youtube.com/watch?v=xxxxx”
注:如果视频字幕是zh-TW,就要把 sub-lang换成 zh-TW,否则就会无法下载,因为找不到英文字幕:[info] There are no subtitles for the requested languages。
注:如果你的电脑没有安装chrome,就把 cookies-from-browser 换成brave:ERROR: could not find chrome cookies database in “/Users/kaiteinlim/Library/Application Support/Google/Chrome”。
注:一定要放 –skip download,否则命令就会下载视频。
注:放–sleep-interval 3 –max-sleep-interval 6 \ 是为了延迟避免被YouTube限流。
注:在 -o “%(title)s.%(ext)s” \ 用 title,下载的vtt文件才会用视频名称命名。 - 成功下载后,在youtubexj文件夹里面,一个视频个别有一个.vtt文件。
- 建立一个新的文件命名为clean_vtt.py,把以下python代码抄入文件。
import re
import os
from pathlib import Path
input_dir = Path(“.”)
output_dir = Path(“transcripts”)
output_dir.mkdir(exist_ok=True)
def clean_vtt(vtt_path):
with open(vtt_path, “r”, encoding=”utf-8″) as f:
lines = f.readlines()text_lines = [] for line in lines: line = line.strip() # 跳过空行、WEBVTT标头、时间码行、纯数字行(序号) if not line: continue if line.startswith("WEBVTT"): continue if "-->" in line: continue if re.match(r"^\d+$", line): continue # 去掉可能残留的HTML标签,例如<c>、<b>等 line = re.sub(r"<[^>]+>", "", line) text_lines.append(line) # 去掉连续重复的行(自动字幕常见问题:同一句话重复出现) deduped = [] for line in text_lines: if not deduped or deduped[-1] != line: deduped.append(line) return " ".join(deduped)
for vtt_file in input_dir.glob(“*.vtt”):
clean_text = clean_vtt(vtt_file)
output_file = output_dir / (vtt_file.stem + “.txt”)
with open(output_file, “w”, encoding=”utf-8″) as f:
f.write(clean_text)
print(f”✓ {vtt_file.name} → {output_file.name}”)
print(f”\n完成!共处理 {len(list(input_dir.glob(‘*.vtt’)))} 个文件,输出到 {output_dir}/”)
至于接下来我要怎么整理这些含有字幕文件的资料,我还没有想到。
又学到新的知识,谢谢!